Open-source data platform
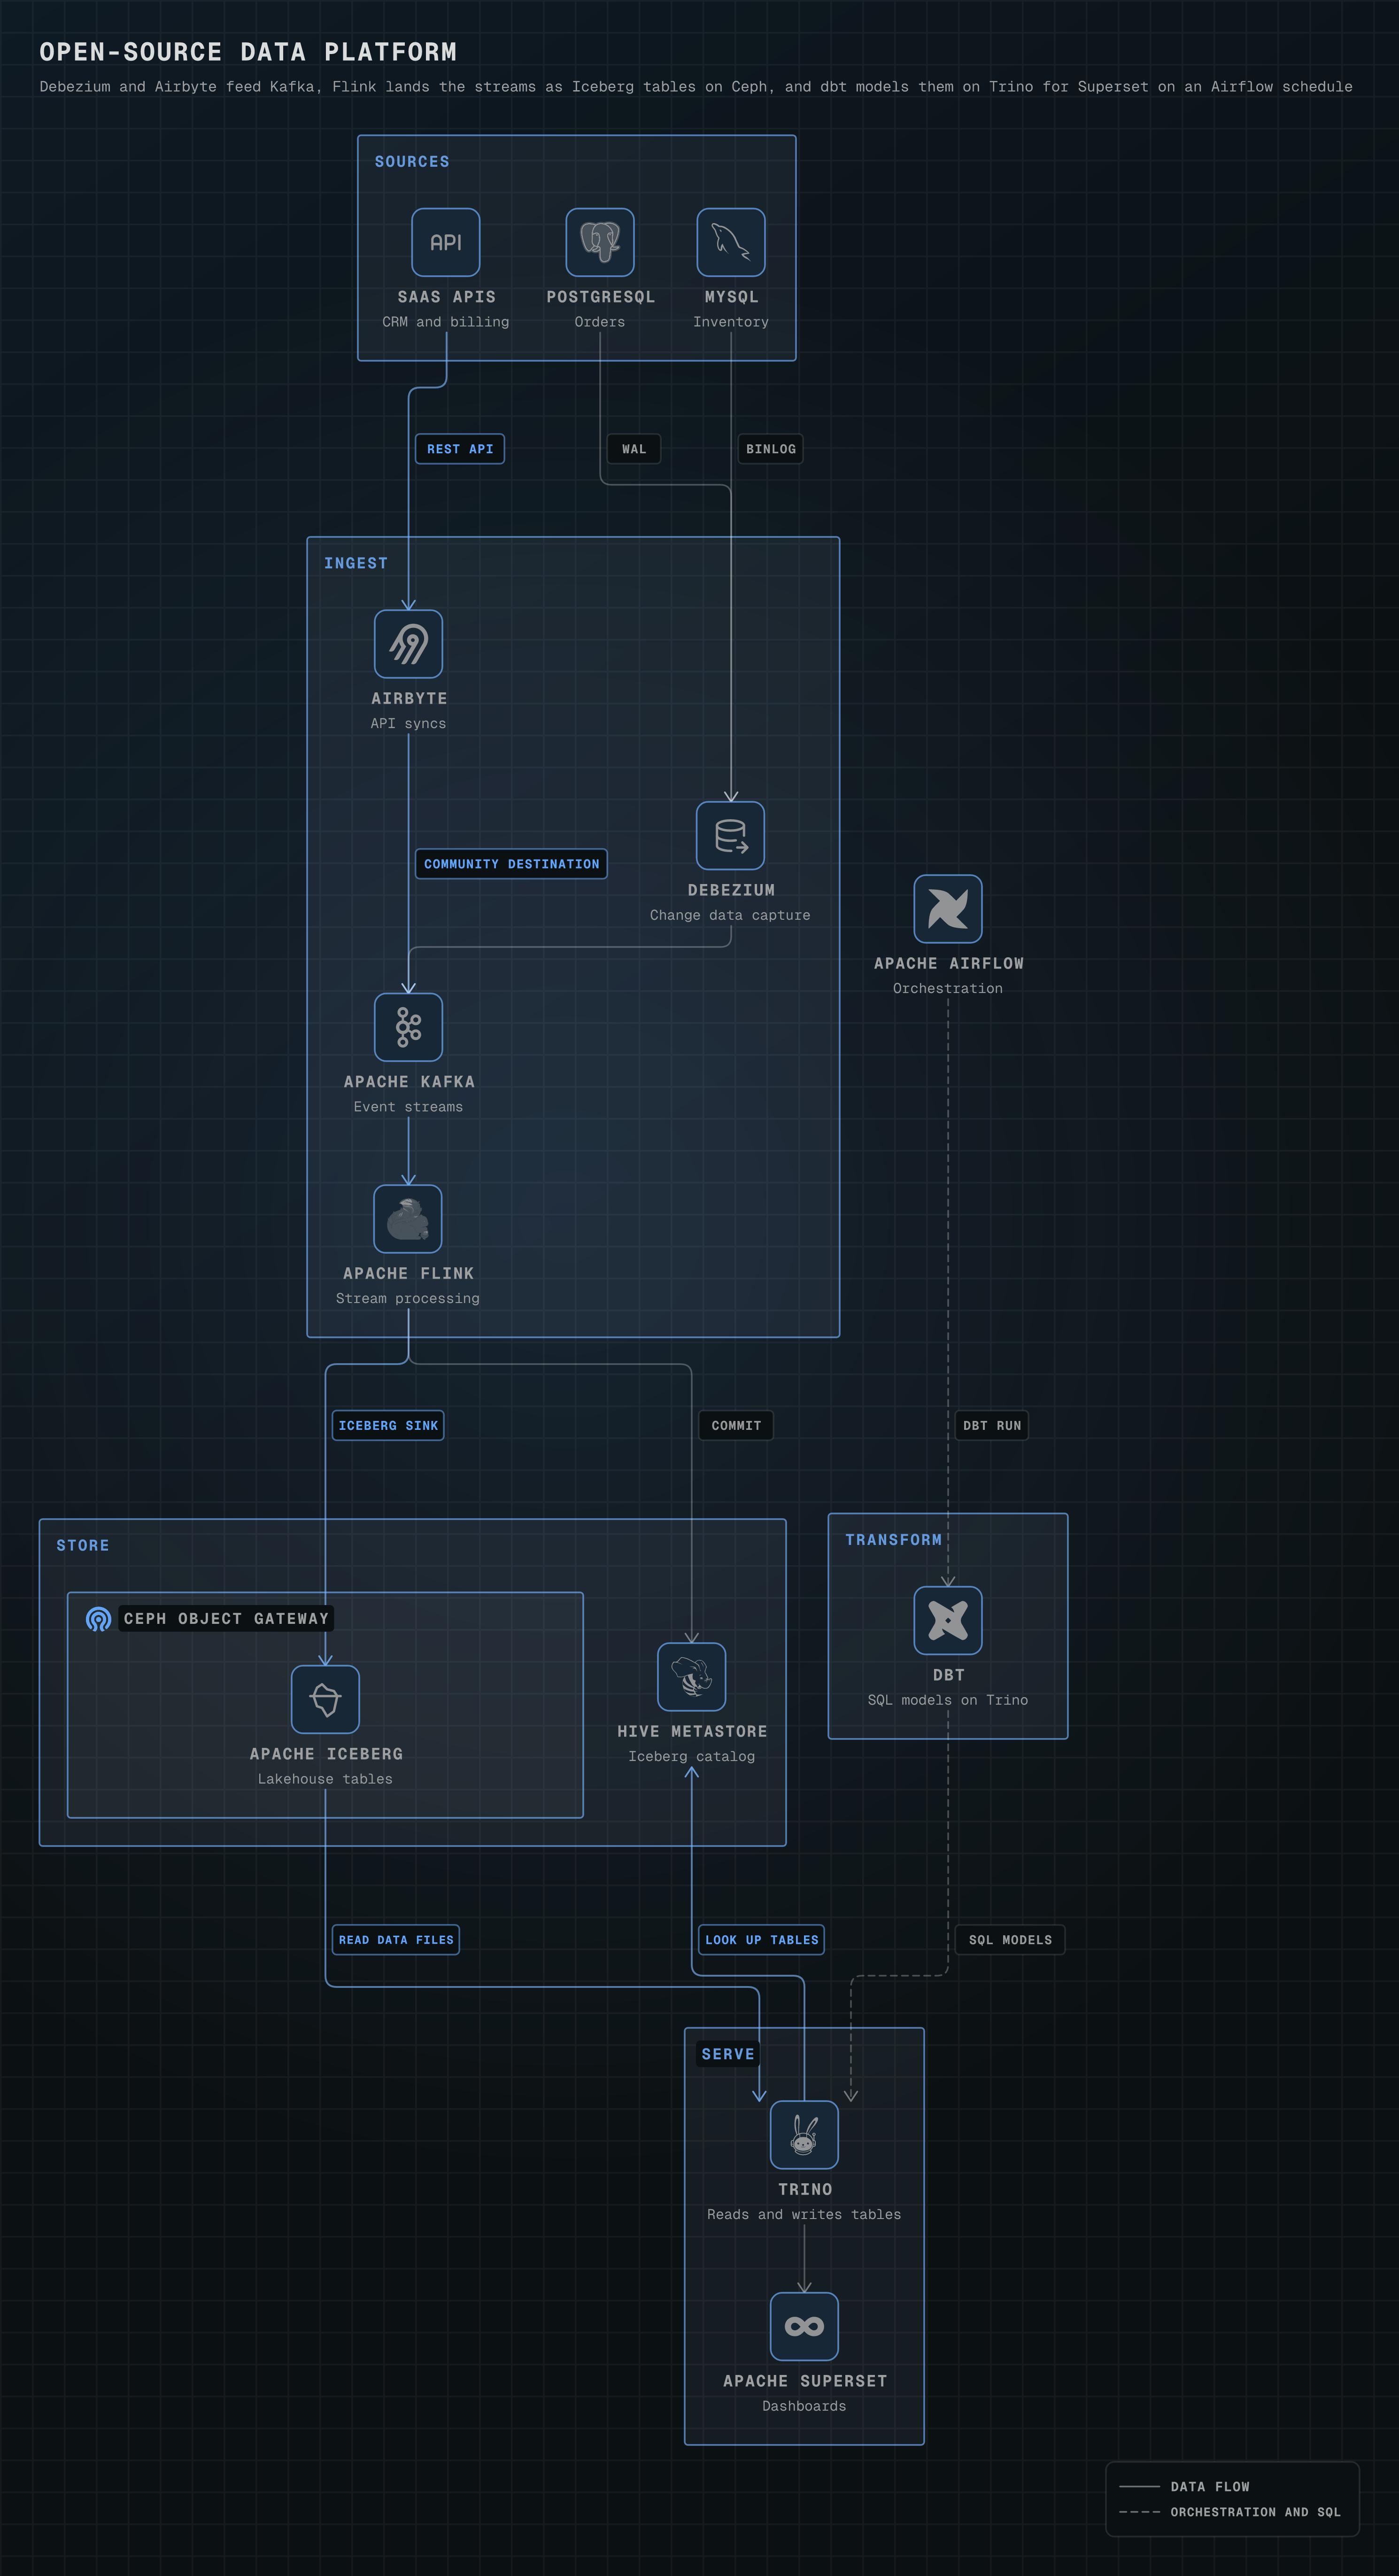
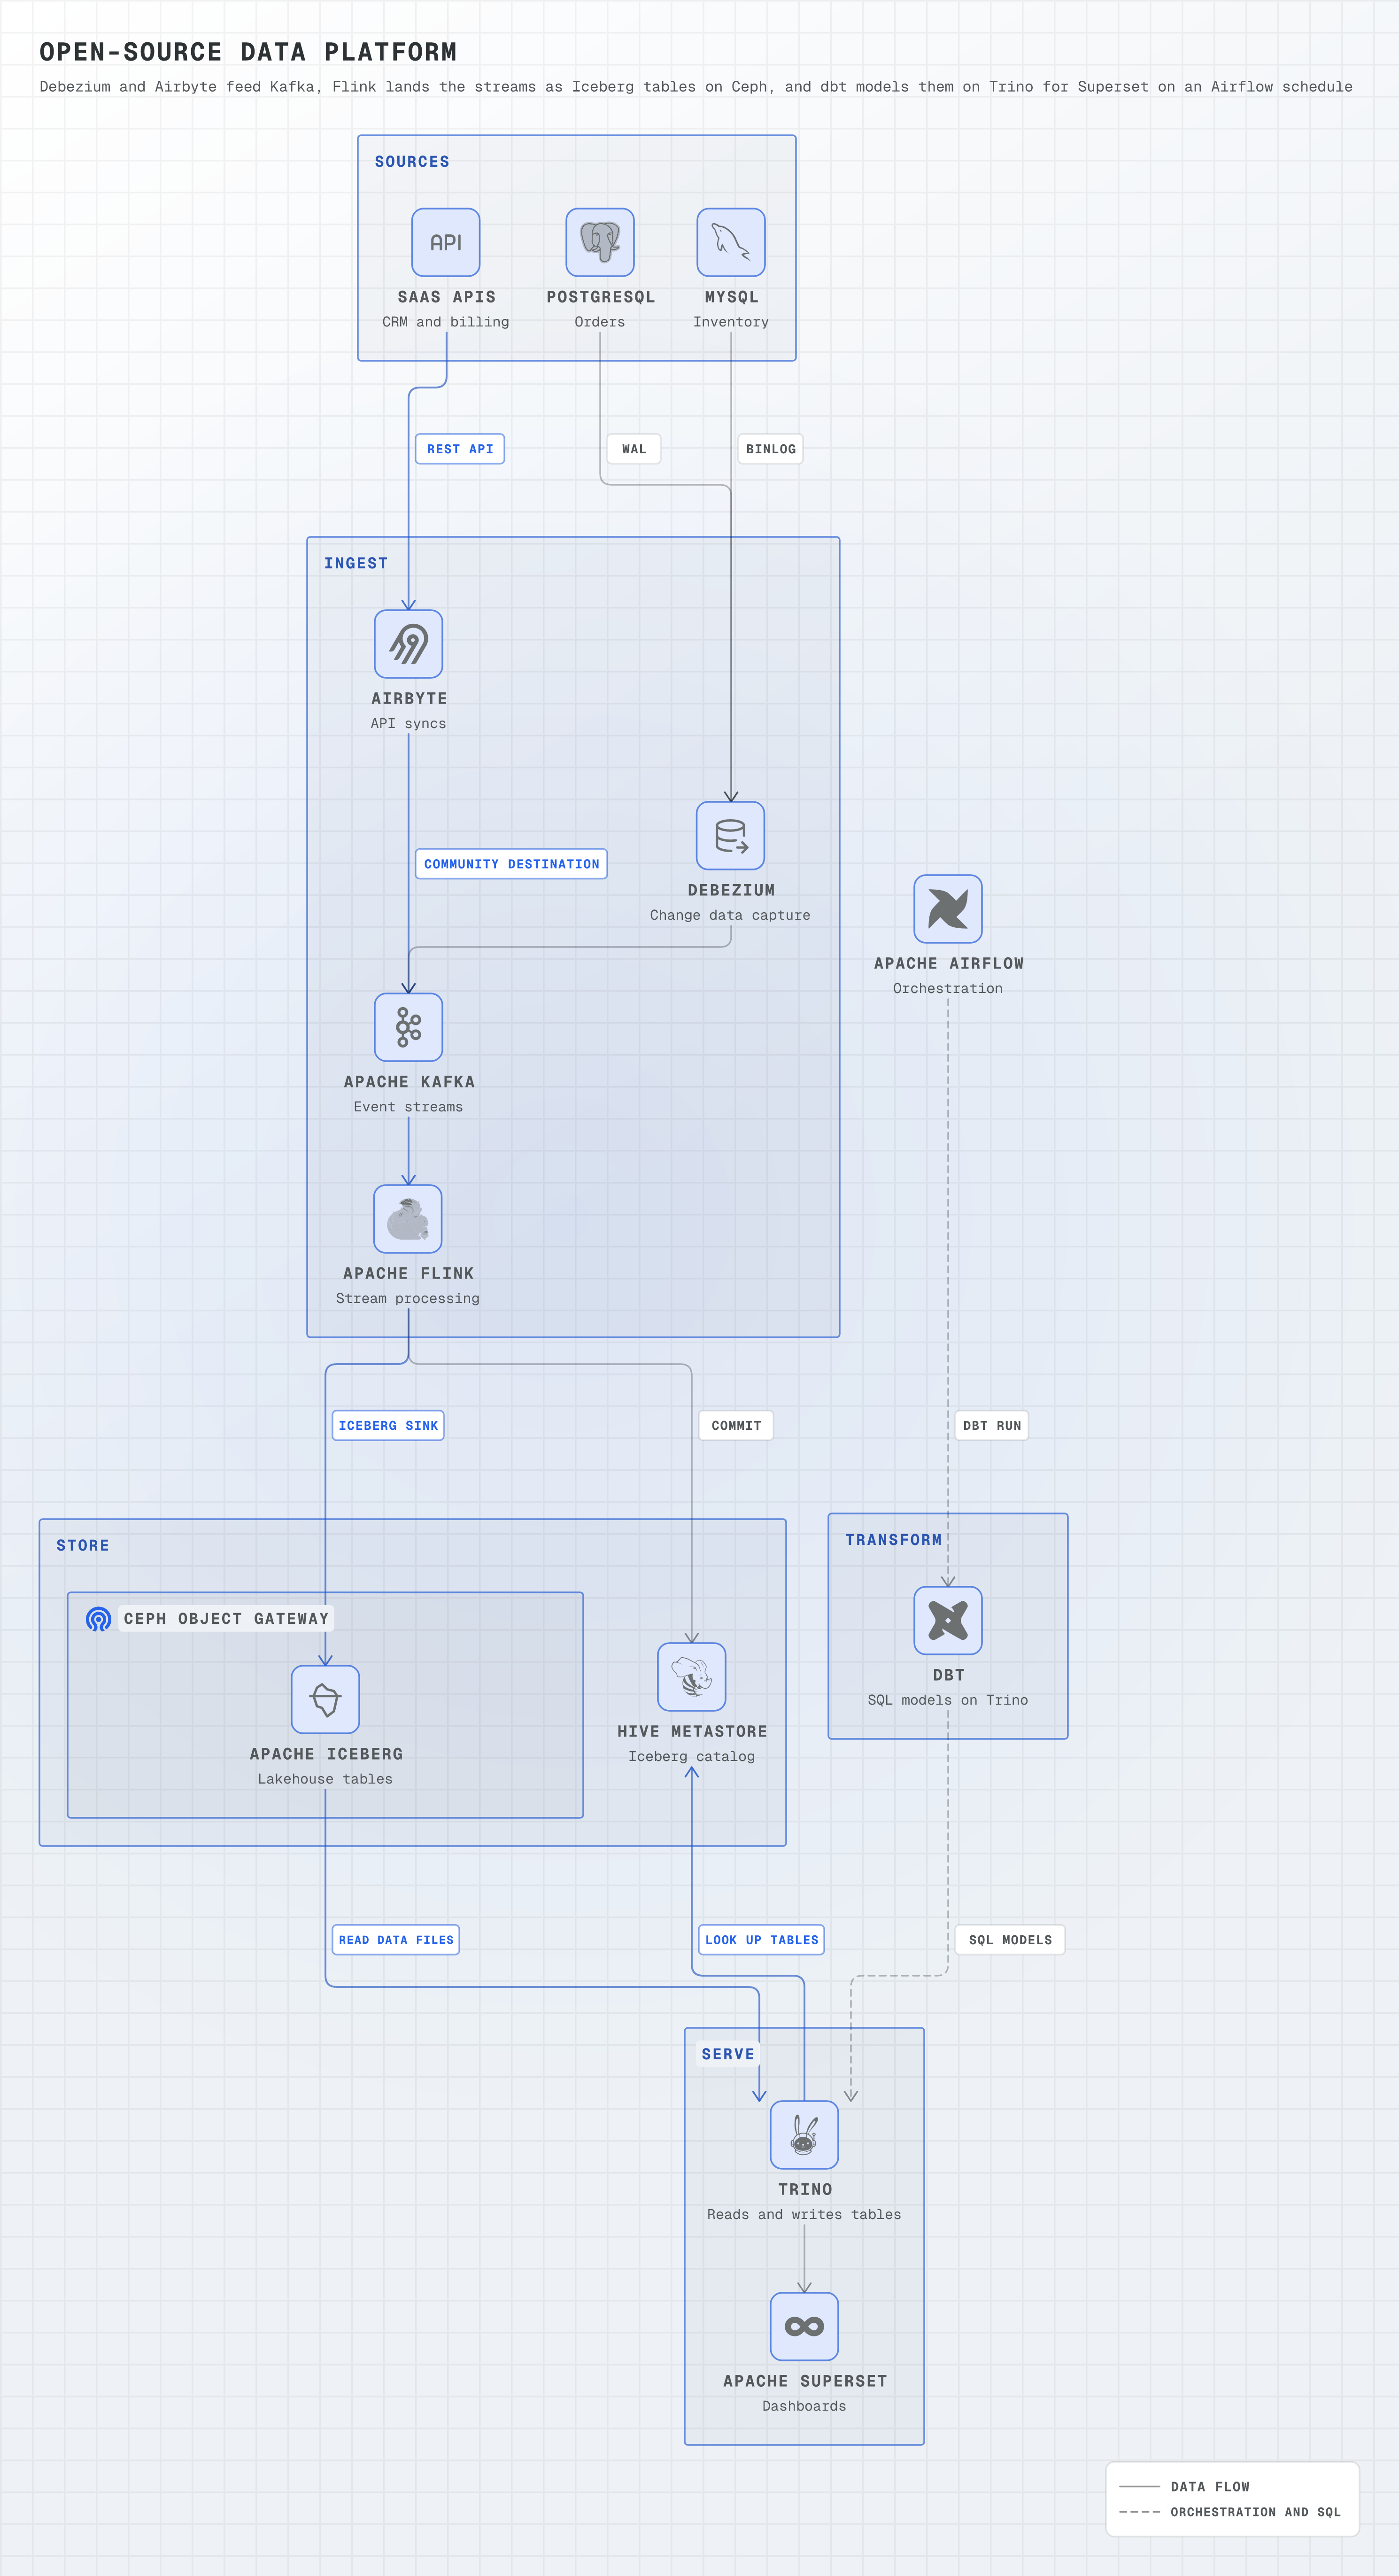
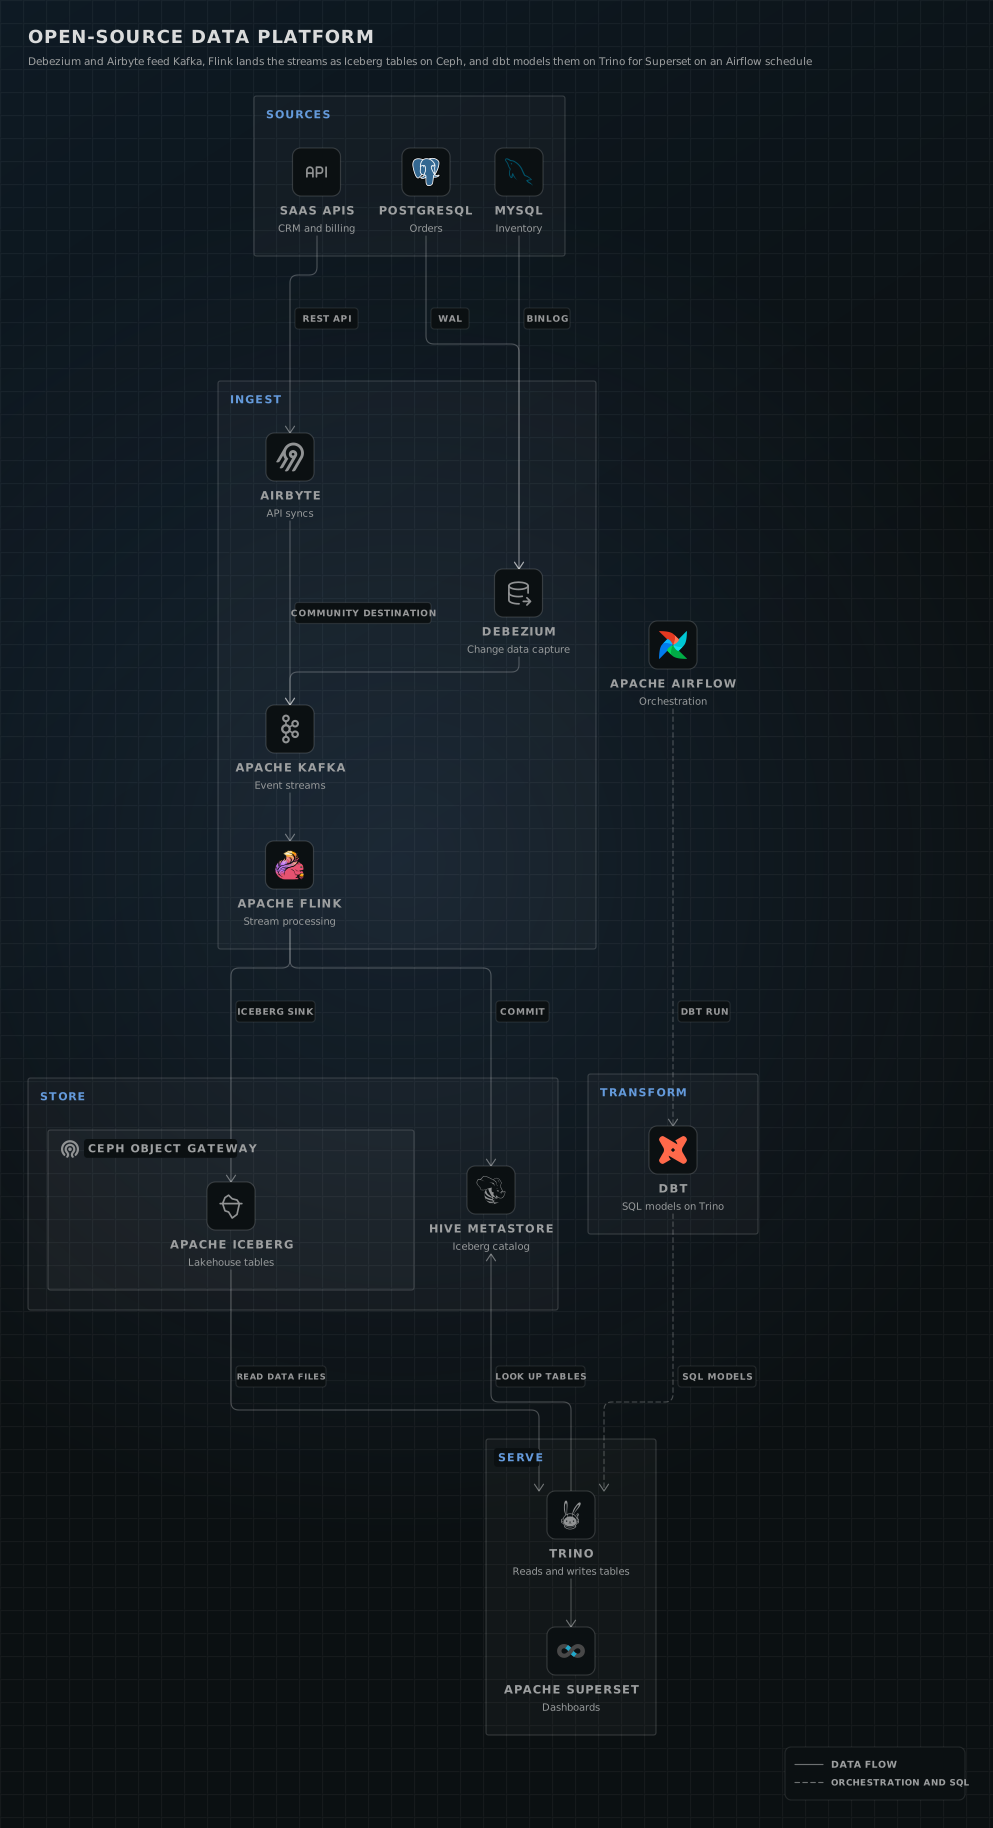
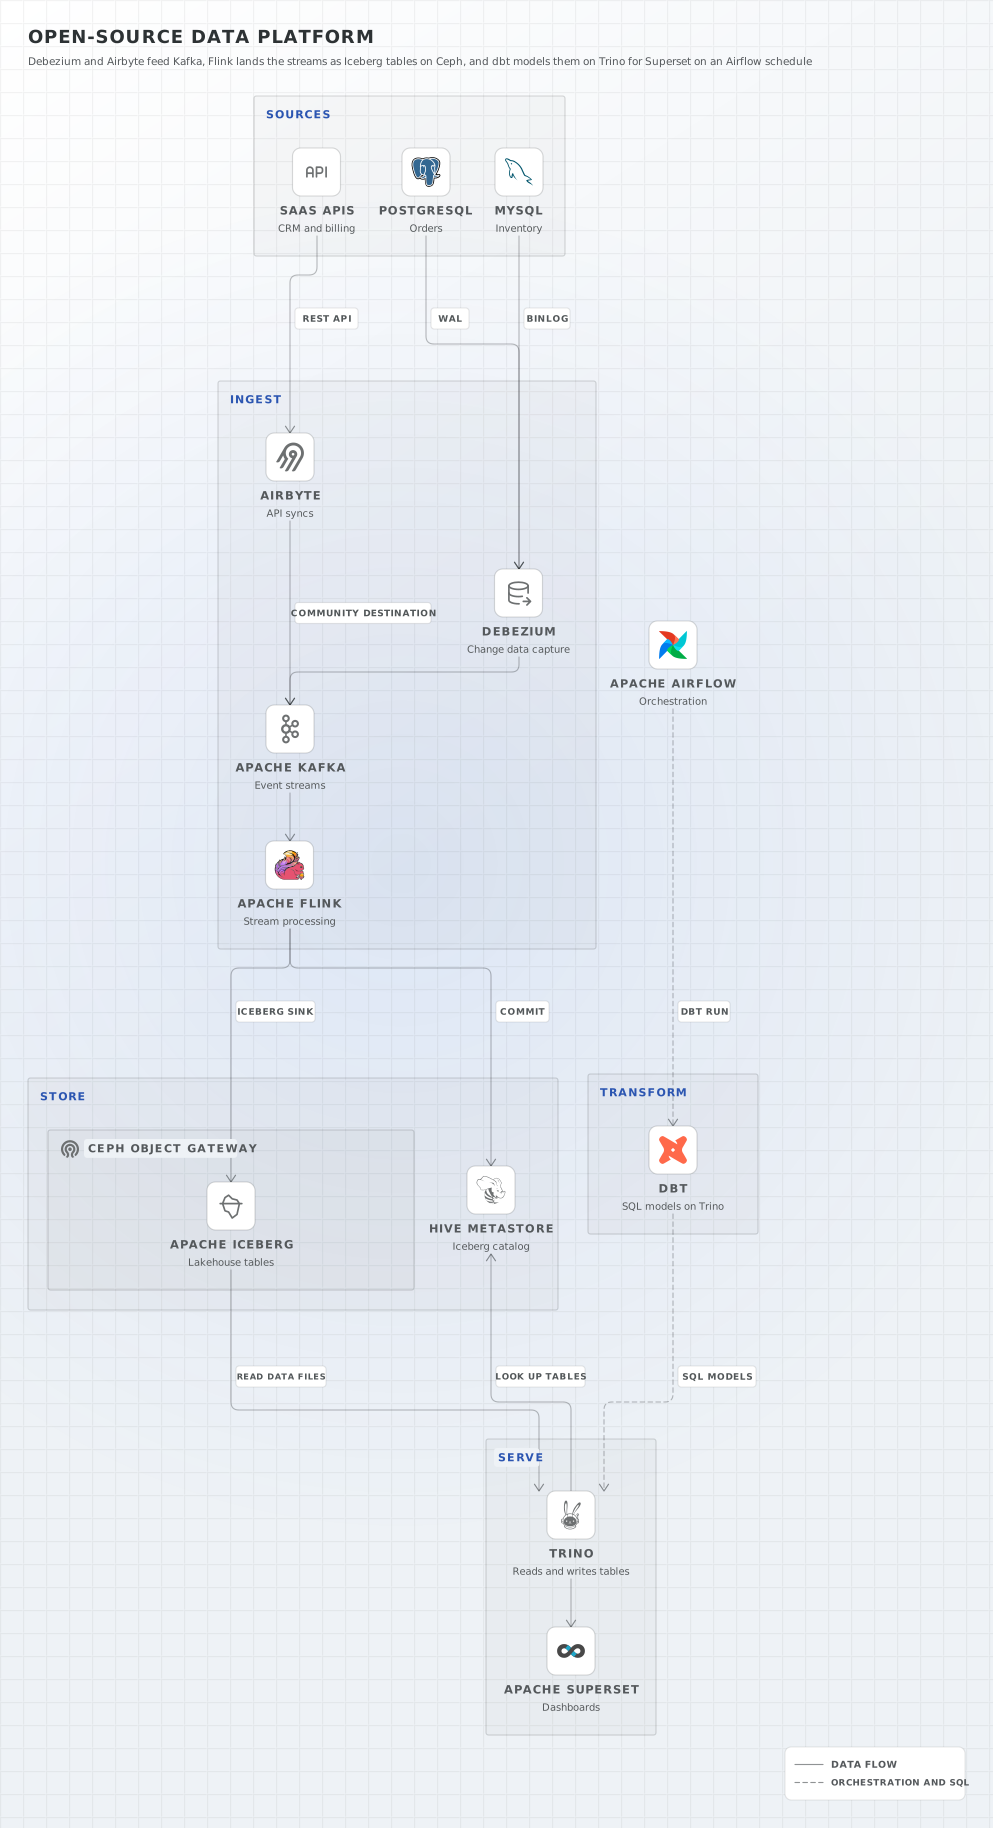
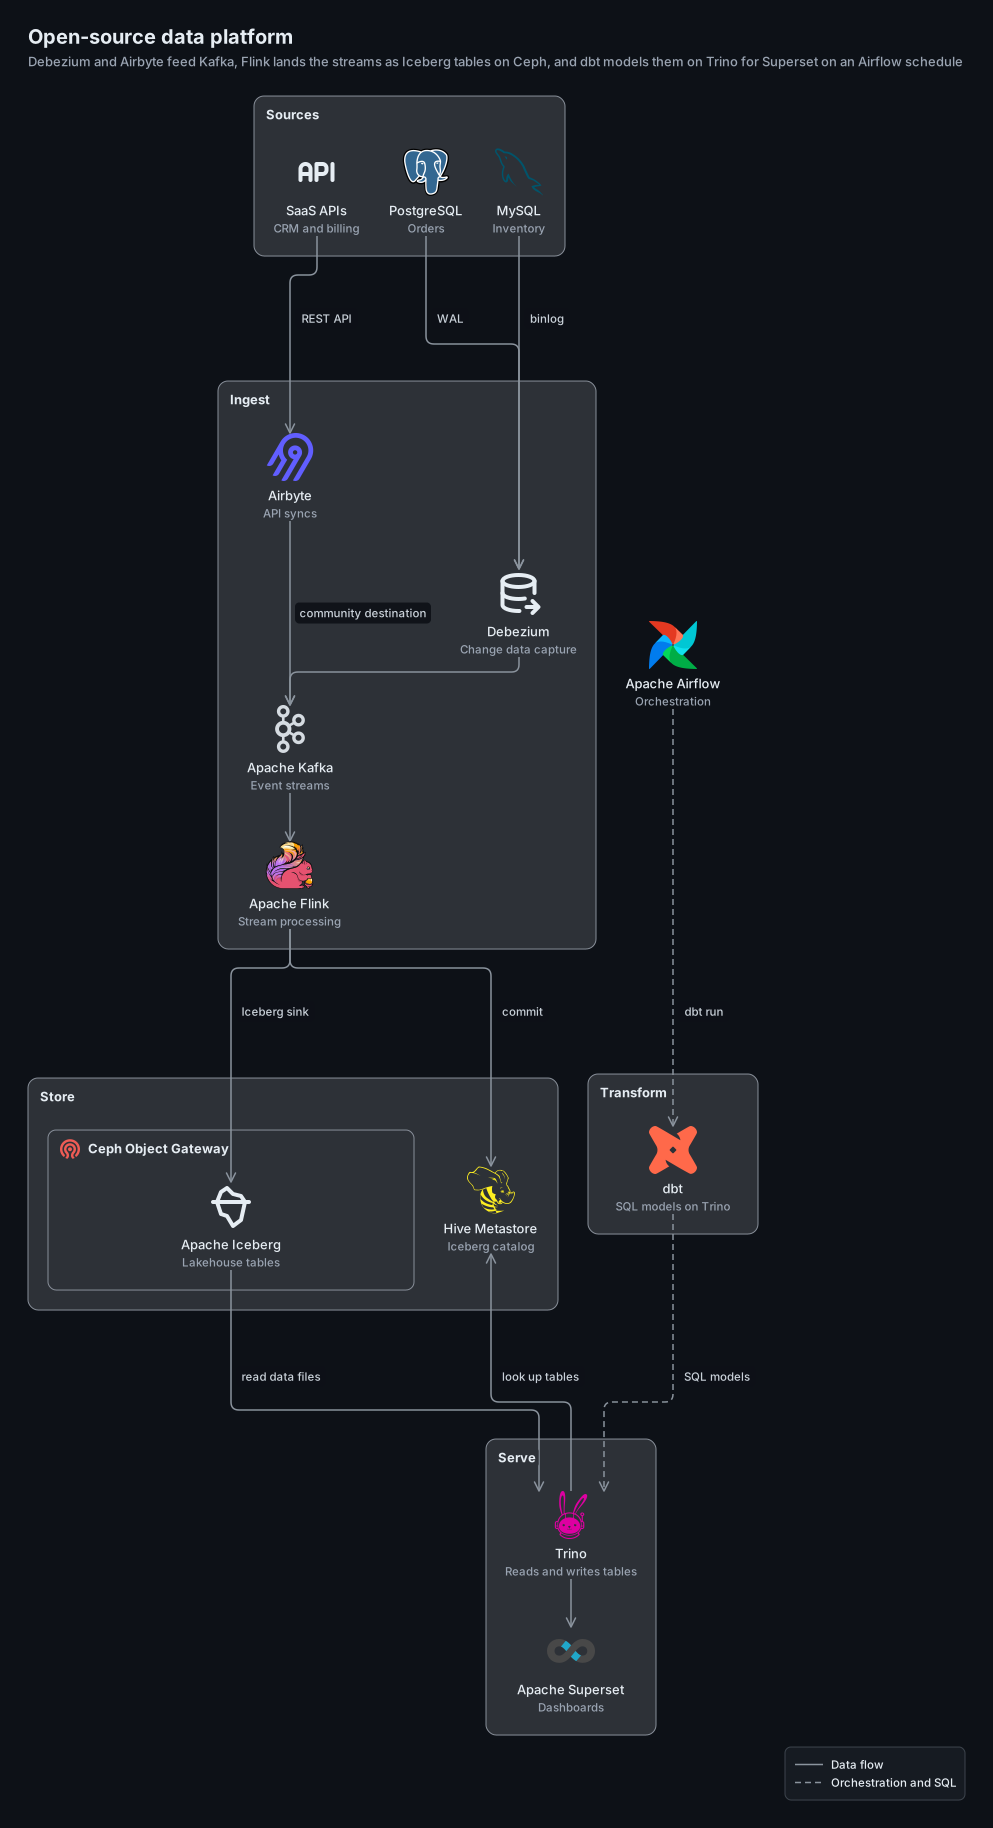
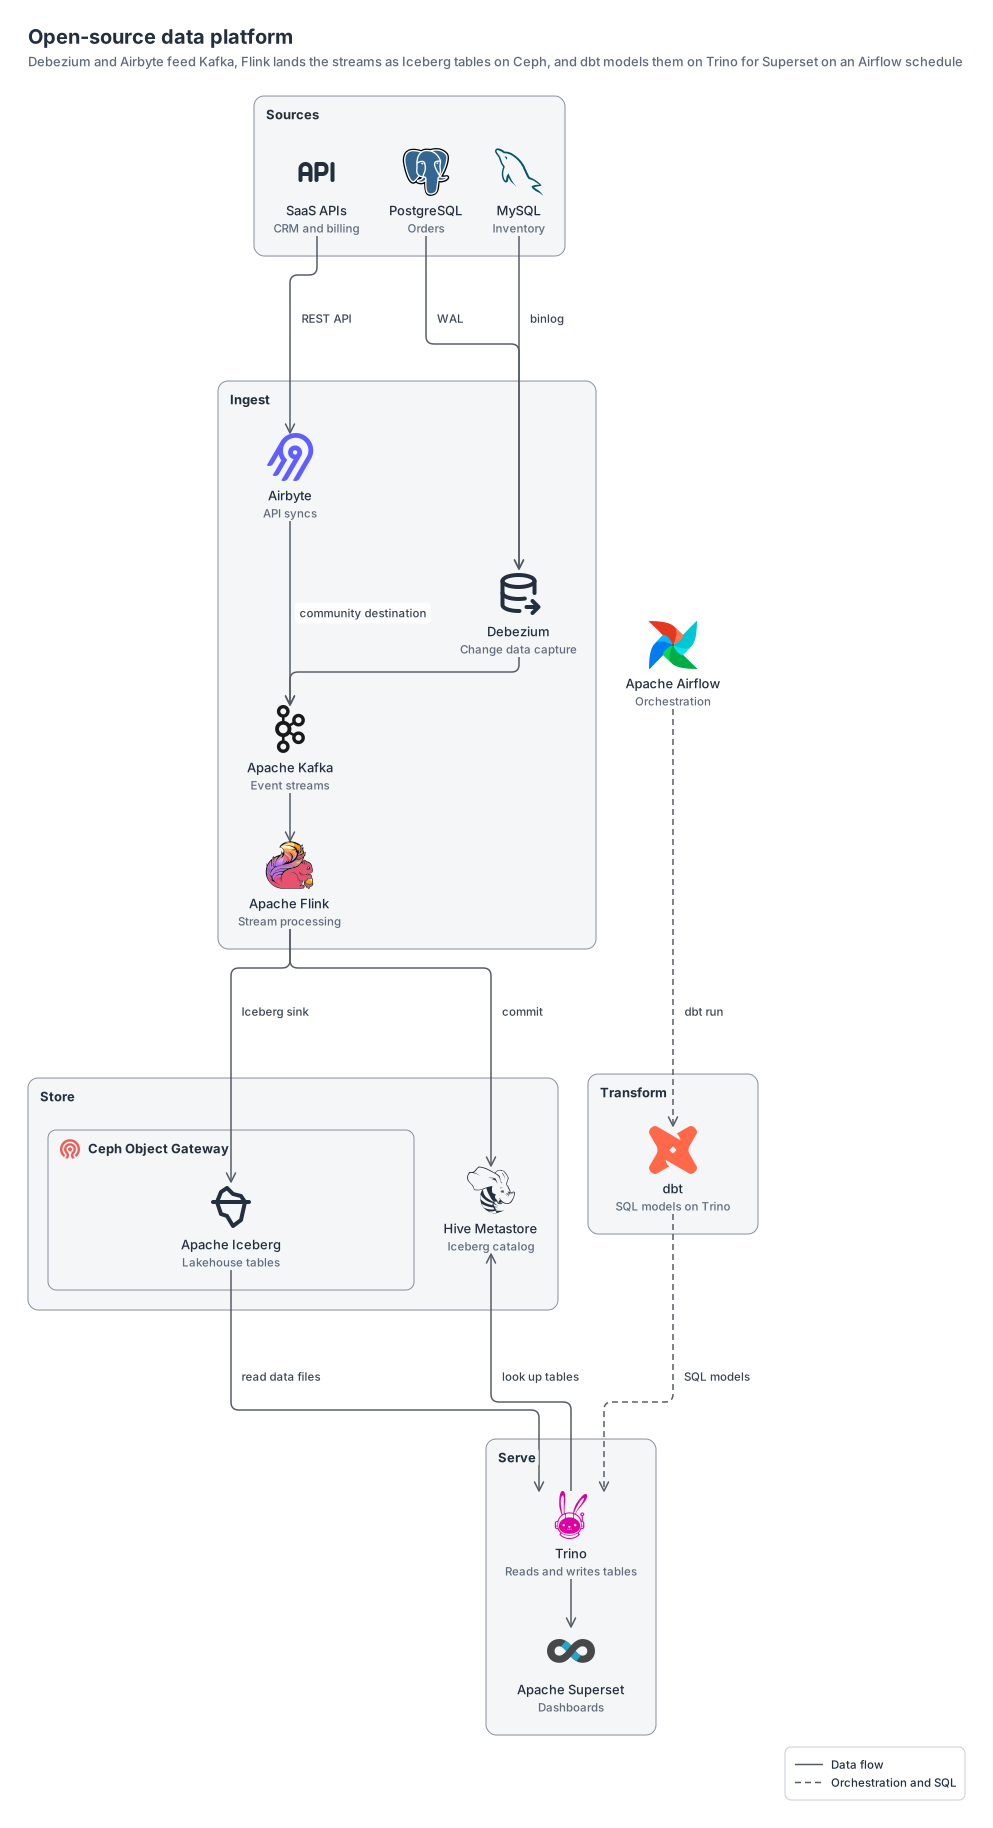
an open-source lakehouse: Debezium and Airbyte feed Kafka, Flink lands Iceberg tables on Ceph with a Hive Metastore catalog, dbt models them on Trino for Superset, on an Airflow schedule.
logossitabler13 nodes6 groups13 edges
data-platform-oss.yamlOn GitHub
# yaml-language-server: $schema=../references/diagram.schema.json
title: Open-source data platform
subtitle: Debezium and Airbyte feed Kafka, Flink lands the streams as Iceberg tables on Ceph, and dbt models them on Trino for Superset on an Airflow schedule
direction: down
layout: { layering: simplex, spacing: compact }

legend:
  solid: Data flow
  dashed: Orchestration and SQL

groups:
  # Top to bottom so the 880px README column shows it at full size. Store is listed before
  # Transform, so Transform sits beside Store and Serve stays on the main column.
  sources: { type: zone, label: Sources }
  ingest: { type: zone, label: Ingest }
  store: { type: zone, label: Store }
  ceph: { type: box, label: Ceph Object Gateway, icon: si:ceph, in: store }
  transform: { type: zone, label: Transform }
  serve: { type: zone, label: Serve }

nodes:
  # Airflow stays outside the zones so Transform stays as narrow as its one node.
  airflow: { icon: logos:airflow-icon, label: Apache Airflow, note: Orchestration }
  dbt: { icon: logos:dbt-icon, label: dbt, note: SQL models on Trino, in: transform }
  saas: { icon: generic:api, label: SaaS APIs, note: CRM and billing, in: sources }
  postgres: { icon: logos:postgresql, label: PostgreSQL, note: Orders, in: sources }
  mysql: { icon: logos:mysql-icon, label: MySQL, note: Inventory, in: sources }
  airbyte: { icon: si:airbyte, label: Airbyte, note: API syncs, in: ingest }
  # No Debezium mark in the packs: a neutral glyph with the product name.
  debezium: { icon: tabler:database-export, label: Debezium, note: Change data capture, in: ingest }
  kafka: { icon: logos:kafka-icon, label: Apache Kafka, note: Event streams, in: ingest }
  flink: { icon: logos:apache-flink-icon, label: Apache Flink, note: Stream processing, in: ingest }
  iceberg: { icon: tabler:iceberg, label: Apache Iceberg, note: Lakehouse tables, in: ceph }
  # Flink and Trino share the Iceberg tables through one catalog.
  catalog: { icon: si:apachehive, label: Hive Metastore, note: Iceberg catalog, in: store }
  trino: { icon: si:trino, label: Trino, note: Reads and writes tables, in: serve }
  superset: { icon: logos:apache-superset-icon, label: Apache Superset, note: Dashboards, in: serve }

edges:
  - saas -> airbyte: REST API
  - airbyte -> kafka: community destination
  - postgres -> debezium: WAL
  - mysql -> debezium: binlog
  - debezium -> kafka
  - kafka -> flink
  - flink -> iceberg: Iceberg sink
  - flink -> catalog: commit
  - iceberg -> trino: read data files
  # Laid out catalog -> Trino so the catalog stays left of Trino; the arrowhead stays on the catalog.
  - { from: catalog, to: trino, arrow: start, label: look up tables }
  - airflow --> dbt: dbt run
  - dbt --> trino: SQL models
  - trino -> superset
Start from this one
Copies the spec to diagram.yaml, then renders every format.
$ orrery init data-platform-oss$ orrery render diagram.yaml -f all --theme both